
/models
Overview
The /models command opens the model selection interface where you can view available AI models grouped by provider and select which model Apex uses for penetration testing.
Usage
How It Works
The models interface displays all available models from your configured providers, organized by provider name. You can navigate through the list and select your preferred model.
When no model is explicitly selected, Apex automatically picks a default based on your configured provider, prioritized as: Pensar → Anthropic → OpenAI → Google → OpenRouter → Bedrock.
Only models from configured providers are shown. Use /providers to set
up additional AI providers, or /login to connect via Pensar Console.
Interface
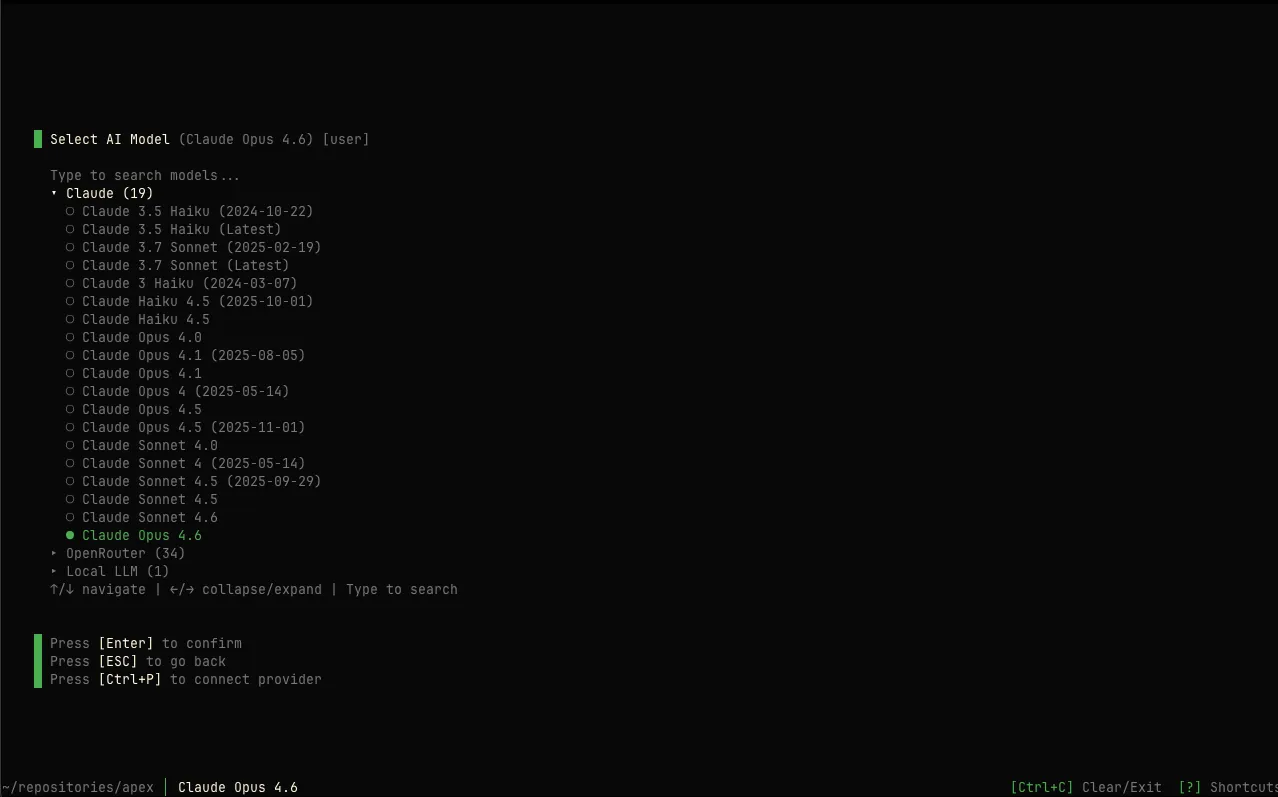
When you open /models, you’ll see:
- Provider sections: Models grouped by provider (Anthropic, OpenAI, Google, etc.)
- Model list: Available models under each provider
- Selection indicator: Current model highlighted with a bullet (●)
- Show more/less: Expand to see all models if a provider has many
Keyboard Navigation
Supported AI Providers
Anthropic (Recommended)
Best performance for penetration testing tasks.
Available models include:
- Claude Opus 4.8 (Maximum capability)
- Claude Opus 4.7
- Claude Opus 4.6
- Claude Sonnet 4.6
- Claude Sonnet 4.5
- Claude Haiku 4.5
- Claude 3.7 Sonnet
- And more…
Anthropic models are specifically recommended for penetration testing due to their superior reasoning capabilities and context understanding.
OpenAI
Support for GPT and o-series models from OpenAI, including GPT 5.5.
Available models include:
- GPT 5.5
- GPT 5.4 / GPT 5.4 Pro
- GPT 5.2 / GPT 5.2 Pro
- GPT-4.1 / GPT-4.1 mini
- GPT-4o / GPT-4o mini
- o3 / o3-mini / o4-mini
- And more…
Google
Gemini models via Google’s Generative AI API.
Available models include:
- Gemini 2.5 Pro / Flash
- Gemini 2.0 Flash
- And more…
OpenRouter
Access to models from multiple providers through a unified API.
Benefits:
- Single API for multiple providers
- Pay-per-use pricing
- Access to latest models from Anthropic, OpenAI, Google, Meta, and more
AWS Bedrock
Enterprise-grade AI through AWS infrastructure.
Available models:
- Claude models via Bedrock
- Amazon Nova models
- Meta Llama models
- And more…
Requires AWS credentials and Bedrock model access in your region.
Pensar Console
Managed inference through Pensar Console — no API key required.
Available models:
- Claude Opus 4.8
- Claude Opus 4.7
- Claude Opus 4.6 (default for Pensar)
- Claude Sonnet 4.5
- Claude Haiku 4.5
- And more…
Connect via /login in Apex.
Default Model Per Provider
When you haven’t explicitly selected a model, Apex automatically uses the flagship model for your highest-priority configured provider:
This also applies to the headless CLI commands (pensar pentest, pensar targeted-pentest) when the --model flag is not provided.
Setting Up Providers
If no providers are configured, the models screen will show:
Click “Connect provider” or press Ctrl+P to open the provider management interface.
Model Selection
Effort and Extended Thinking
/effort opens the same model picker as /models, from home or an operator
session. It also appears in command autocomplete and help.
The selected model determines which control appears:
- Effort shows only levels known to be supported by that model and provider.
- Extended Thinking appears when a model supports on/off control instead.
- Models with unknown capabilities use their defaults without an adjustable control.
Select a model, then press ←/→ to cycle its settings, even while the search box has focus. Press Enter on a provider to expand or collapse it, or on the selected model again to close the picker. Preferences are saved separately for each model/provider, and sessions retain their selected setting when resumed with the same model.
Default uses the known model default. Where thinking is mandatory, Apex does
not offer an off setting. A level such as high has provider-specific meaning;
it is not a fixed token budget or a prediction of cost.
Headless commands also accept --effort <level> (or --effort default). Models
with a thinking toggle support --extended-thinking and
--no-extended-thinking. Invalid combinations fail before an inference request.
Model Comparison
Performance Considerations
Model performance impacts: - Reasoning quality: How well the AI understands security concepts - Context handling: Ability to track complex test scenarios - Speed: Time to complete testing runs - Cost: Per-token or subscription costs
When to Use Each Model
Troubleshooting
No models available
Issue: No models showing in the selection
Solution:
- Press
Ctrl+Pto open provider management - Configure at least one AI provider with a valid API key
- Return to
/modelsto see available models
Provider not showing models
Issue: Configured provider doesn’t show any models
Solution:
- Verify your API key is valid
- Check your account has credits/access
- For AWS Bedrock, ensure model access is enabled
- Try reconfiguring the provider in
/providers
Model selection not saving
Issue: Selected model doesn’t persist
Solution:
- Ensure you press
[Enter]to confirm selection - Check that you have write permissions to config directory
- Restart Apex and try again